Backend & Cloud
Stock-Exchange Announcements Feed on AWS – Parallel Serverless PDF Parsing
Parallel serverless PDF parsing for a stock-exchange announcements feed.
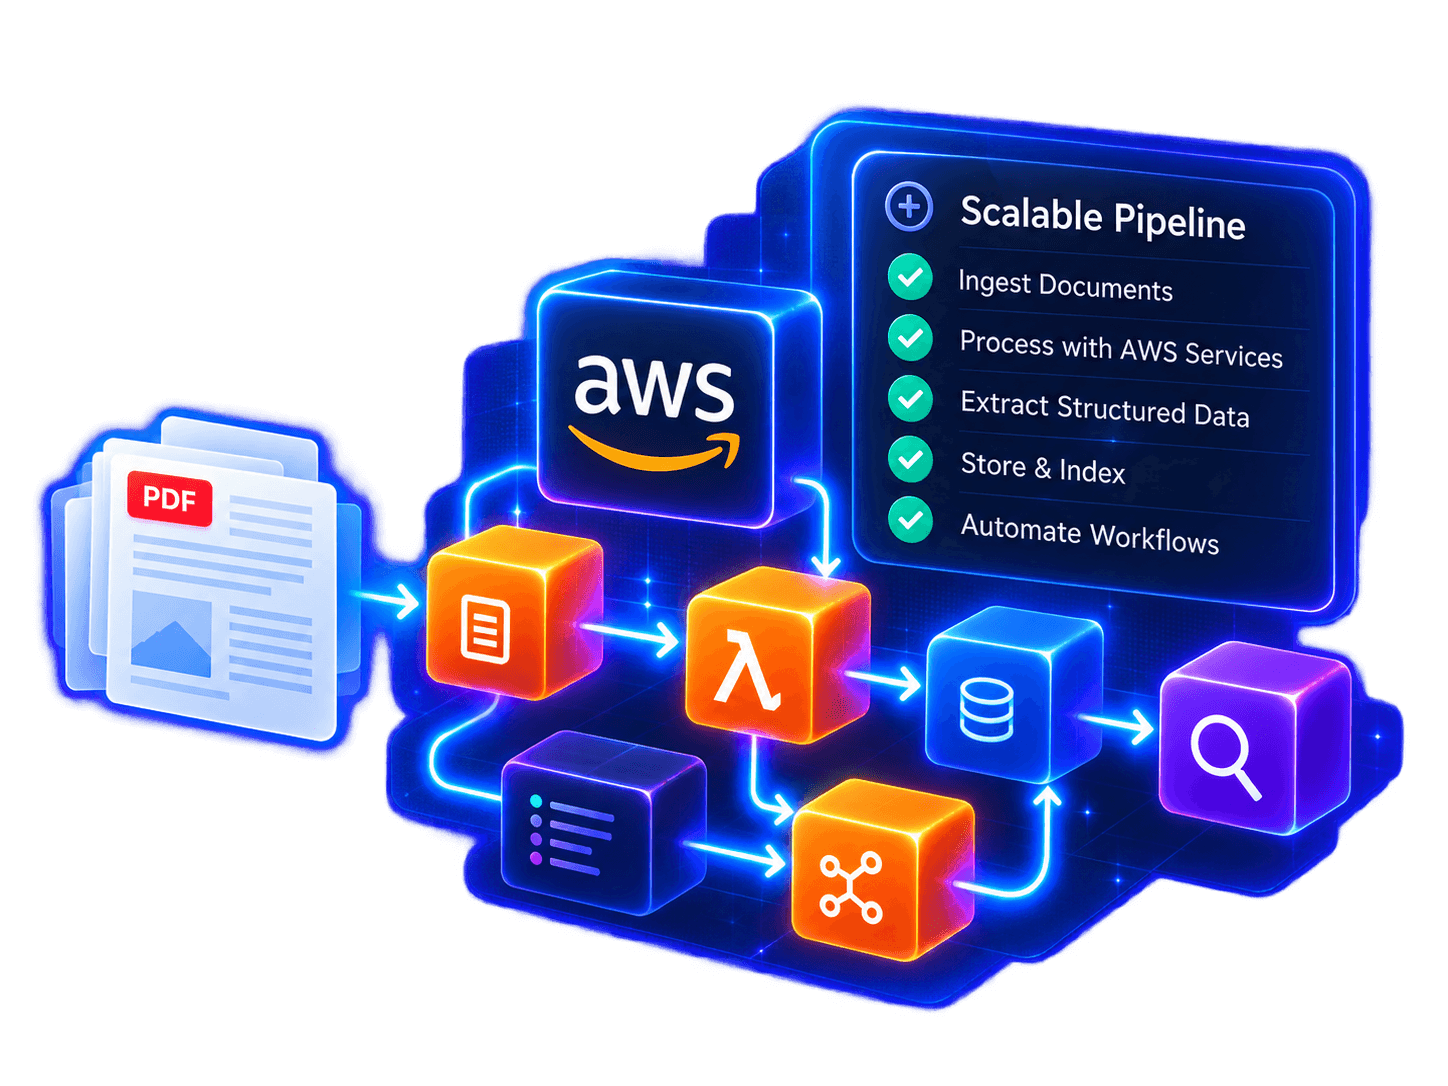
Project Overview
Built an event-driven AWS pipeline that ingests announcement PDFs and metadata files from an exchange FTP feed (synced to S3 every minute over an IPsec VPN) and parses each document in parallel: a splitter groups pages into chunks, Lambda workers extract them with one reused converter, and a merger writes data, tables and summary JSON. Idempotent DynamoDB claims prevent reprocessing, S3 chunk manifests removed the page limit on large PDFs, and Google Vision OCR with a combined per-document JSON completes delivery.
Tools & Technologies: AWS Lambda · Step Functions · S3 · EventBridge · DynamoDB · ECR · Docker · Python · Docling · Google Cloud Vision OCR · IPsec VPN · FTP
Event-driven ingestion
Parallel extraction
Duplicate-work prevention
Large-document support
Project capabilities are described from recorded experience. Artwork uses illustrative sample data.
Need a similar system?
Let’s discuss how I can help build a solution around your documents, data, and workflows.
More to explore
All projects →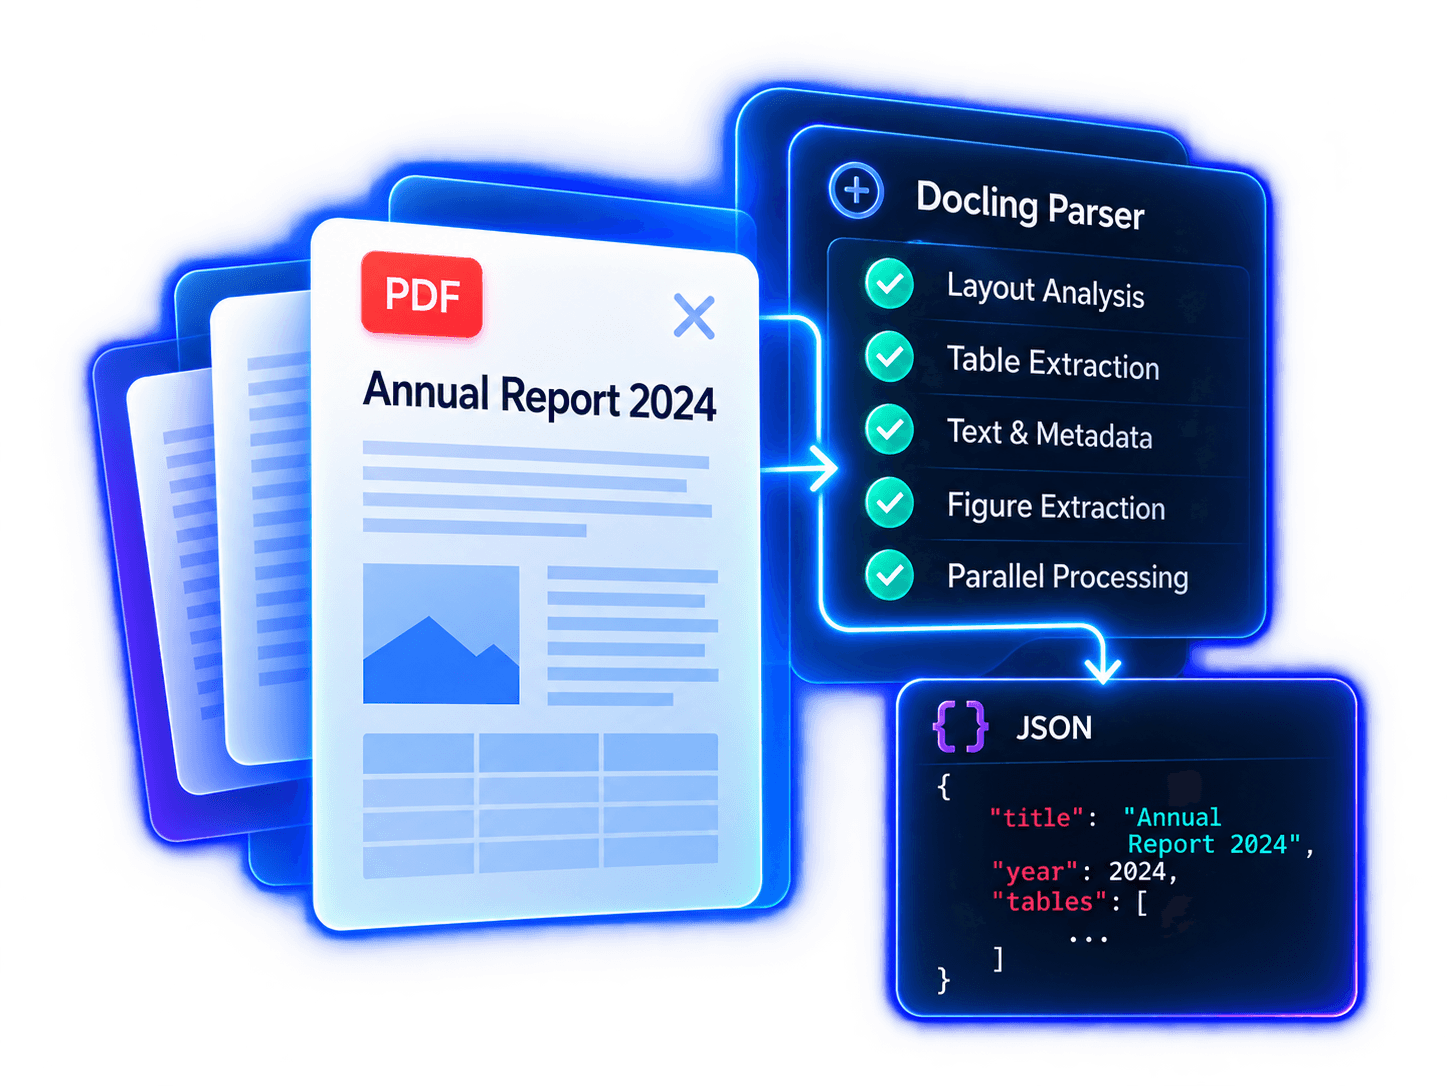
Global Filings PDF Parser
Real-time text, headings, and financial-table extraction from global filings.
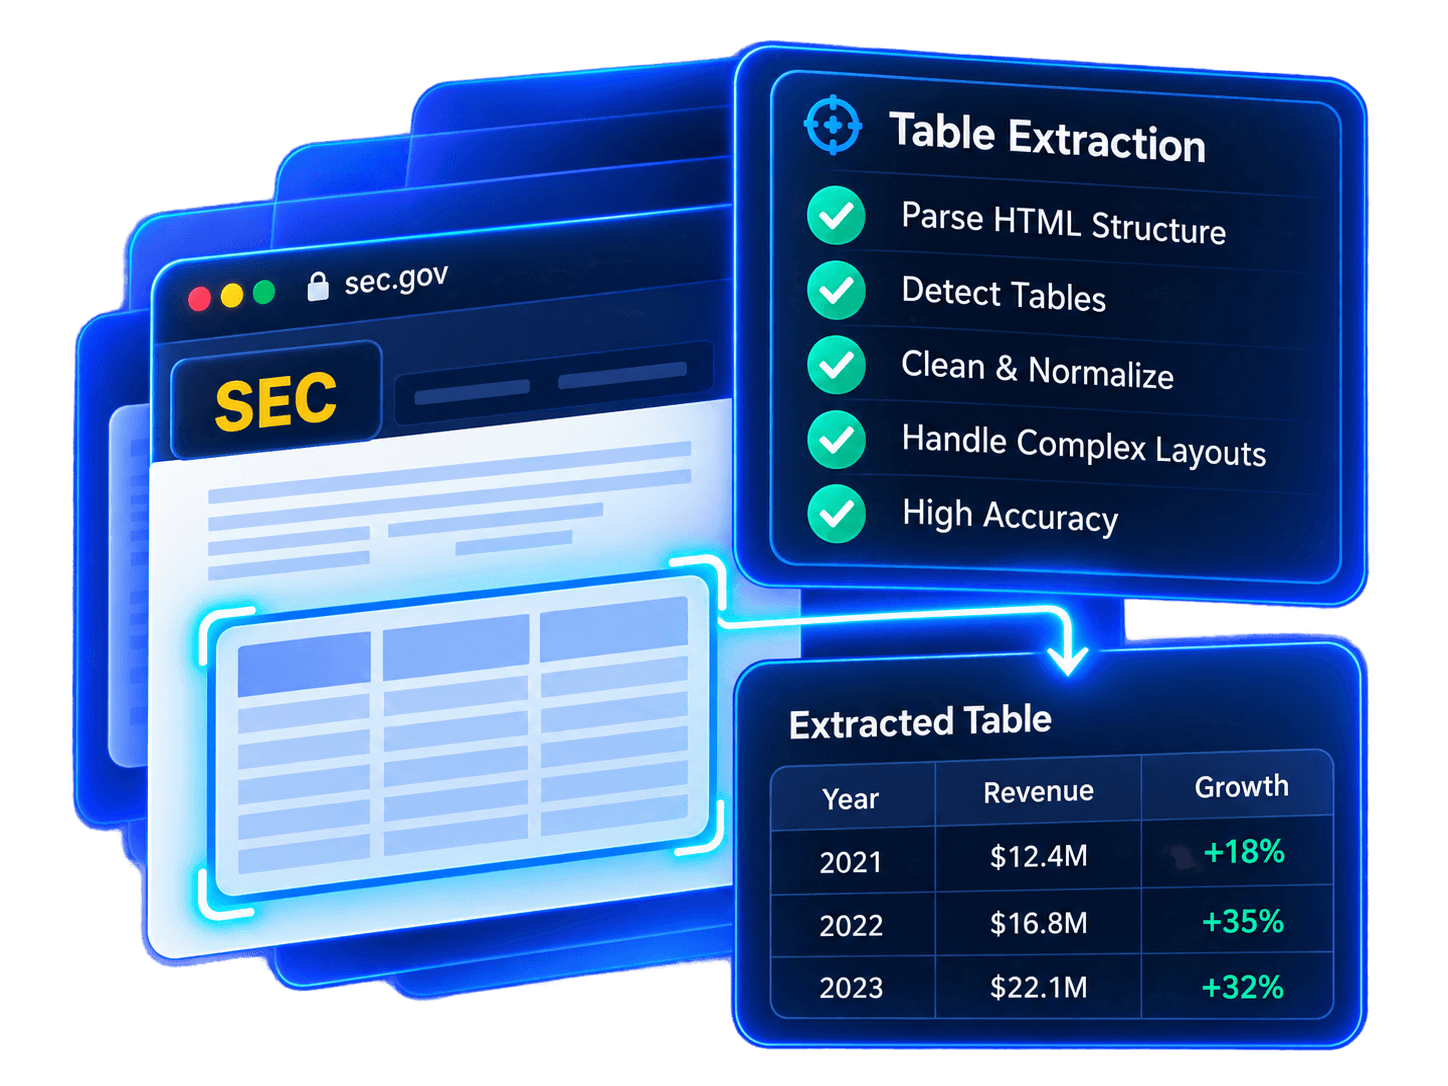
SEC Filings Table Extraction
Semantic financial-table JSON from live SEC filings and the 2006–2026 archive.
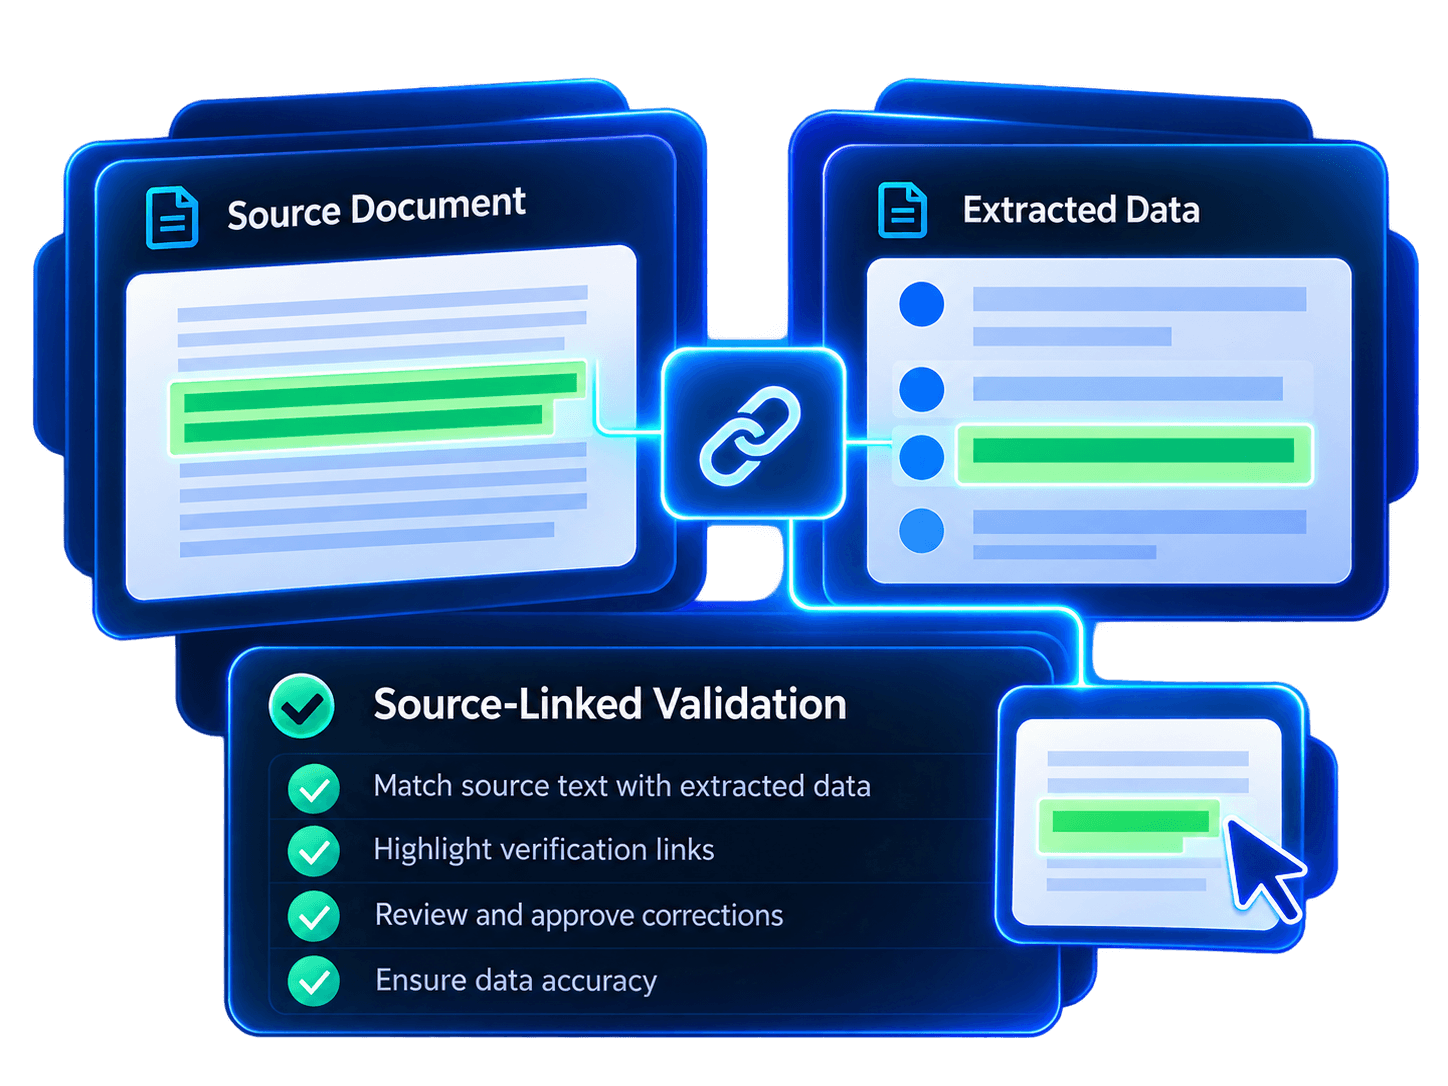
Extracted-Table Review Portal
Source-linked PDF comparisons, table review views, and structured-output inspection.