Project overview
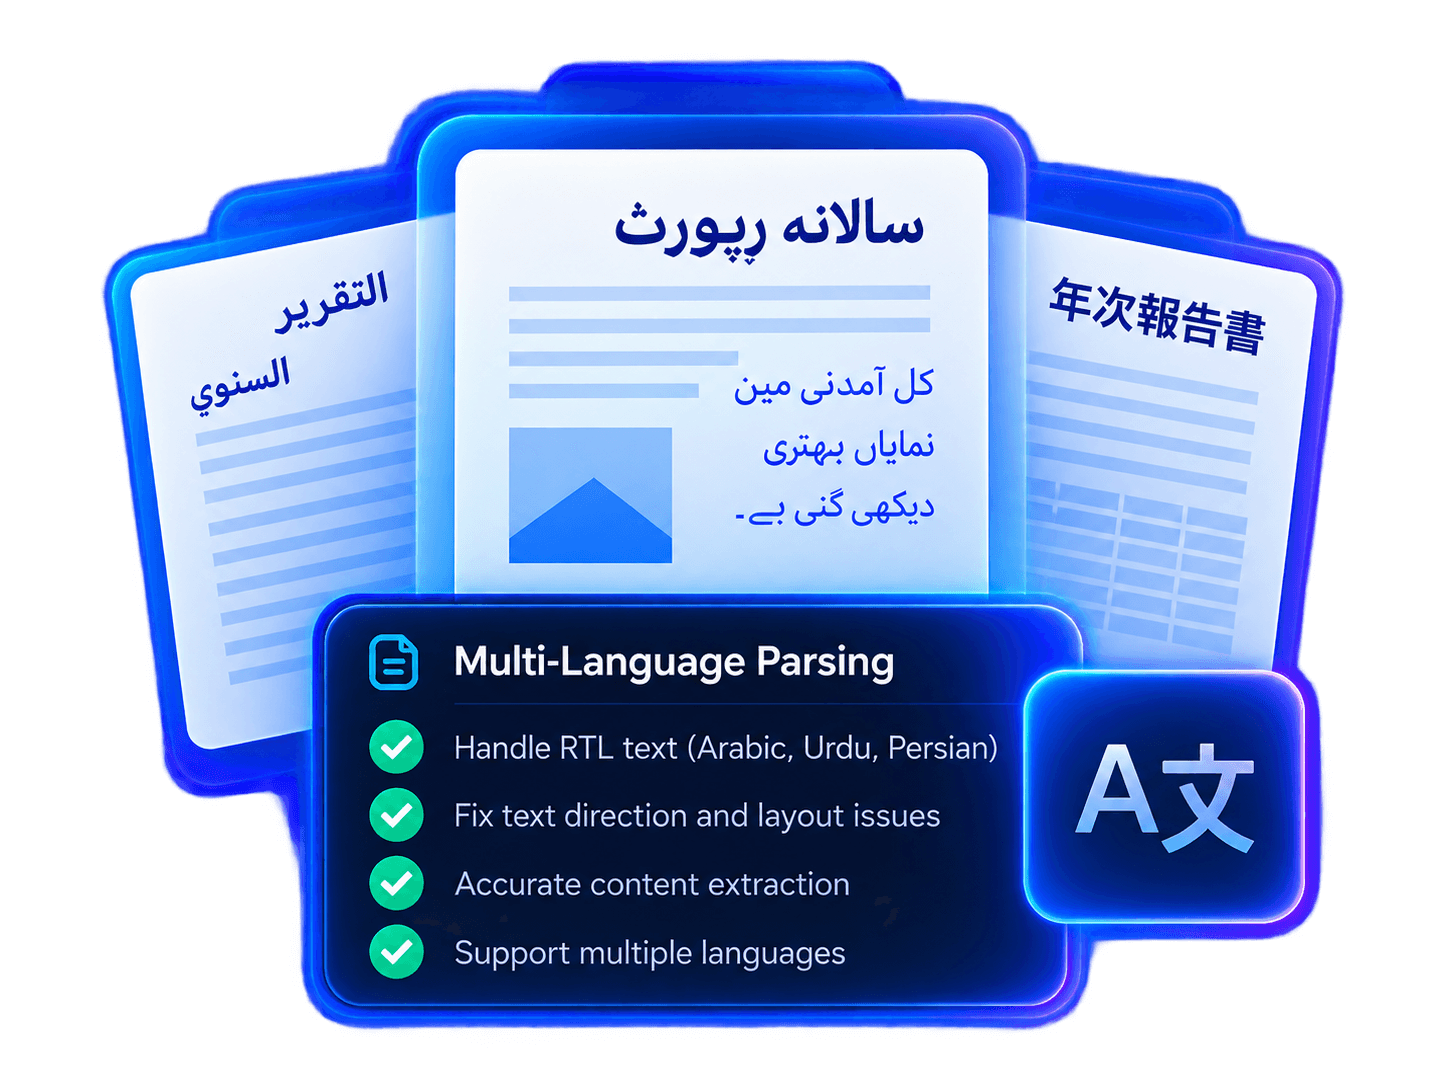
Some financial PDFs store Hebrew or Arabic glyphs in visual order. Sorting characters by their horizontal position can spell a word backwards. I used glyph boxes to reconstruct lines, applied the Unicode Bidirectional Algorithm and compared the result with the source page. The work also addressed truncated Hebrew headings and separate character corruption issues in Japanese and Korean filings.
The engineering problem
The visual order of text in a PDF can differ from reading order. Naive character sorting can reverse words or corrupt headings.
My contribution
- Worked on Hebrew/Arabic text reconstruction from PDF geometry.
- Applied bidirectional text handling to reading-order problems.
- Resolved heading and glyph corruption issues.
- Investigated Japanese and Korean extraction defects.
 Worked on Hebrew/Arabic text reconstruction from PDF geometry.
How the system works
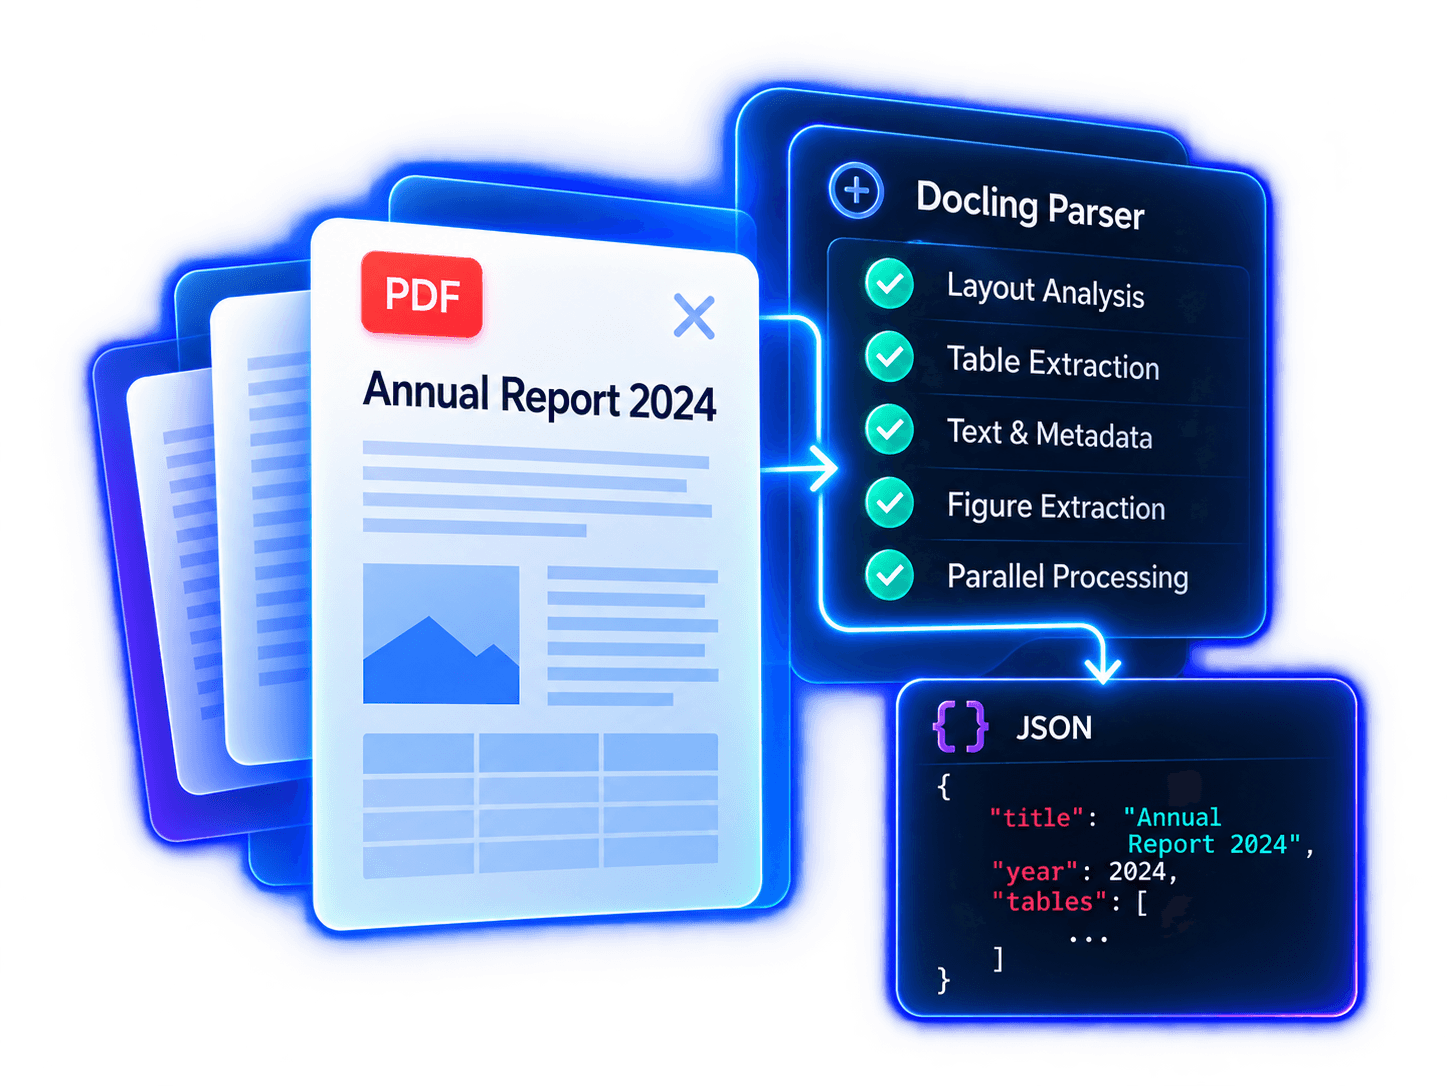
- Inspect text layers and character geometry.
- Reconstruct lines and determine their reading direction.
- Apply bidirectional ordering and heading fixes.
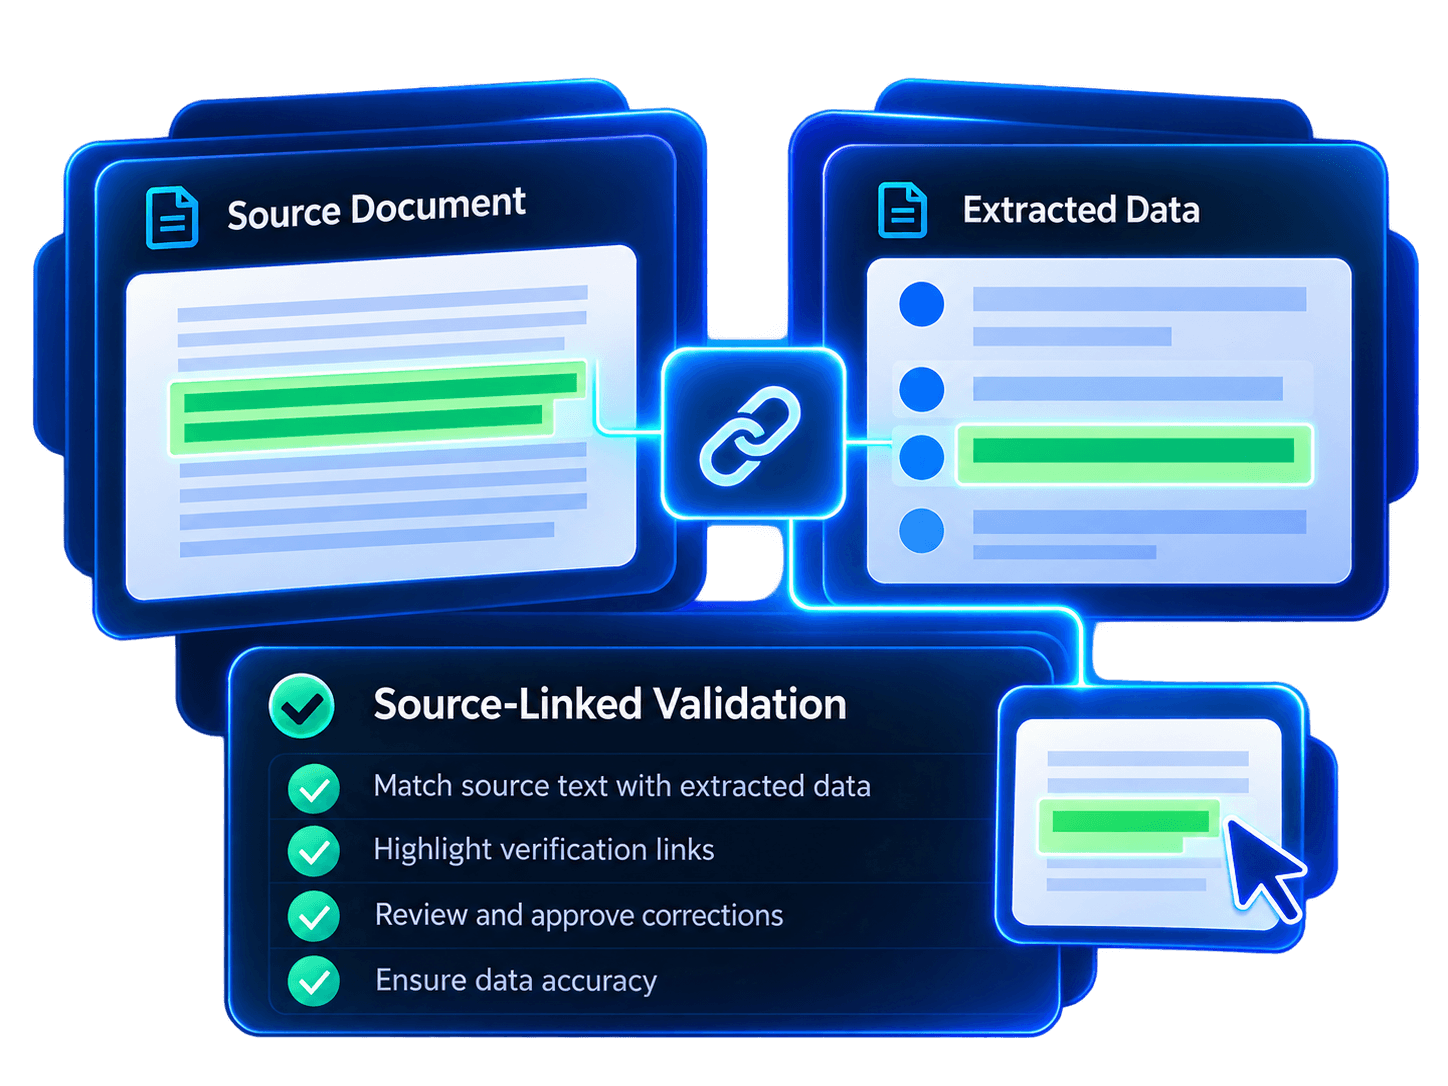
- Compare extraction results with the source document.
Tools & Technologies
Python · pypdfium2 · Unicode Bidirectional Algorithm (UAX #9) · Docling · Node.js · Java
Delivered capabilities
RTL reconstruction
Reading-order fixes
Heading repairs
Non-Latin support
Project illustrations use sample data.