Project overview
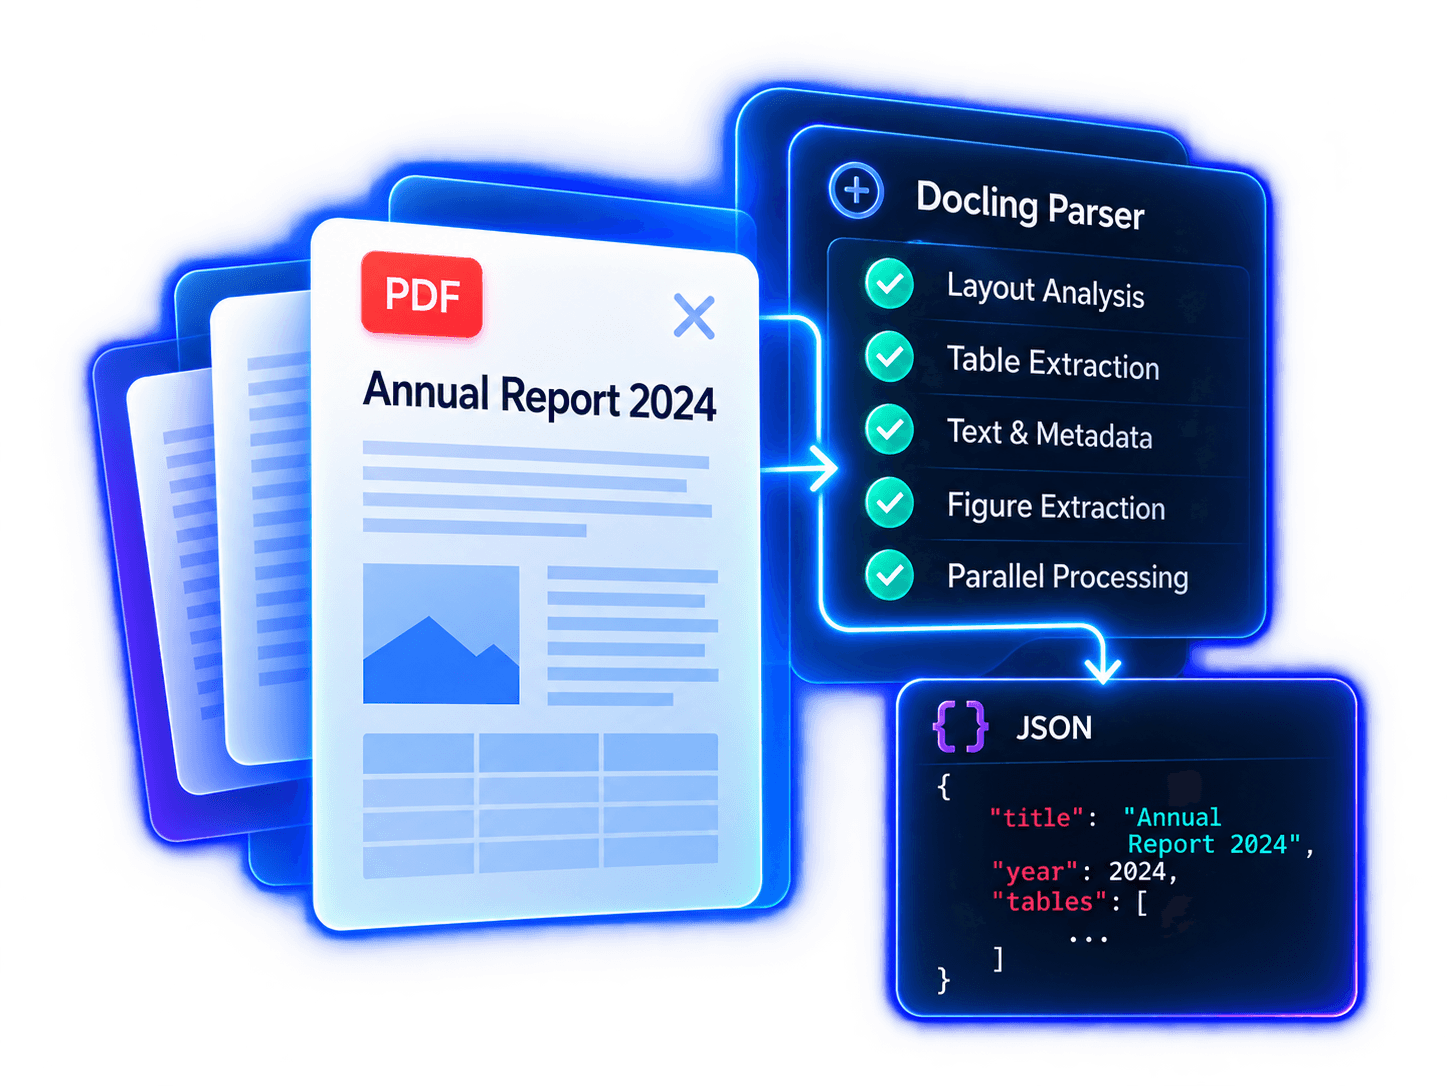
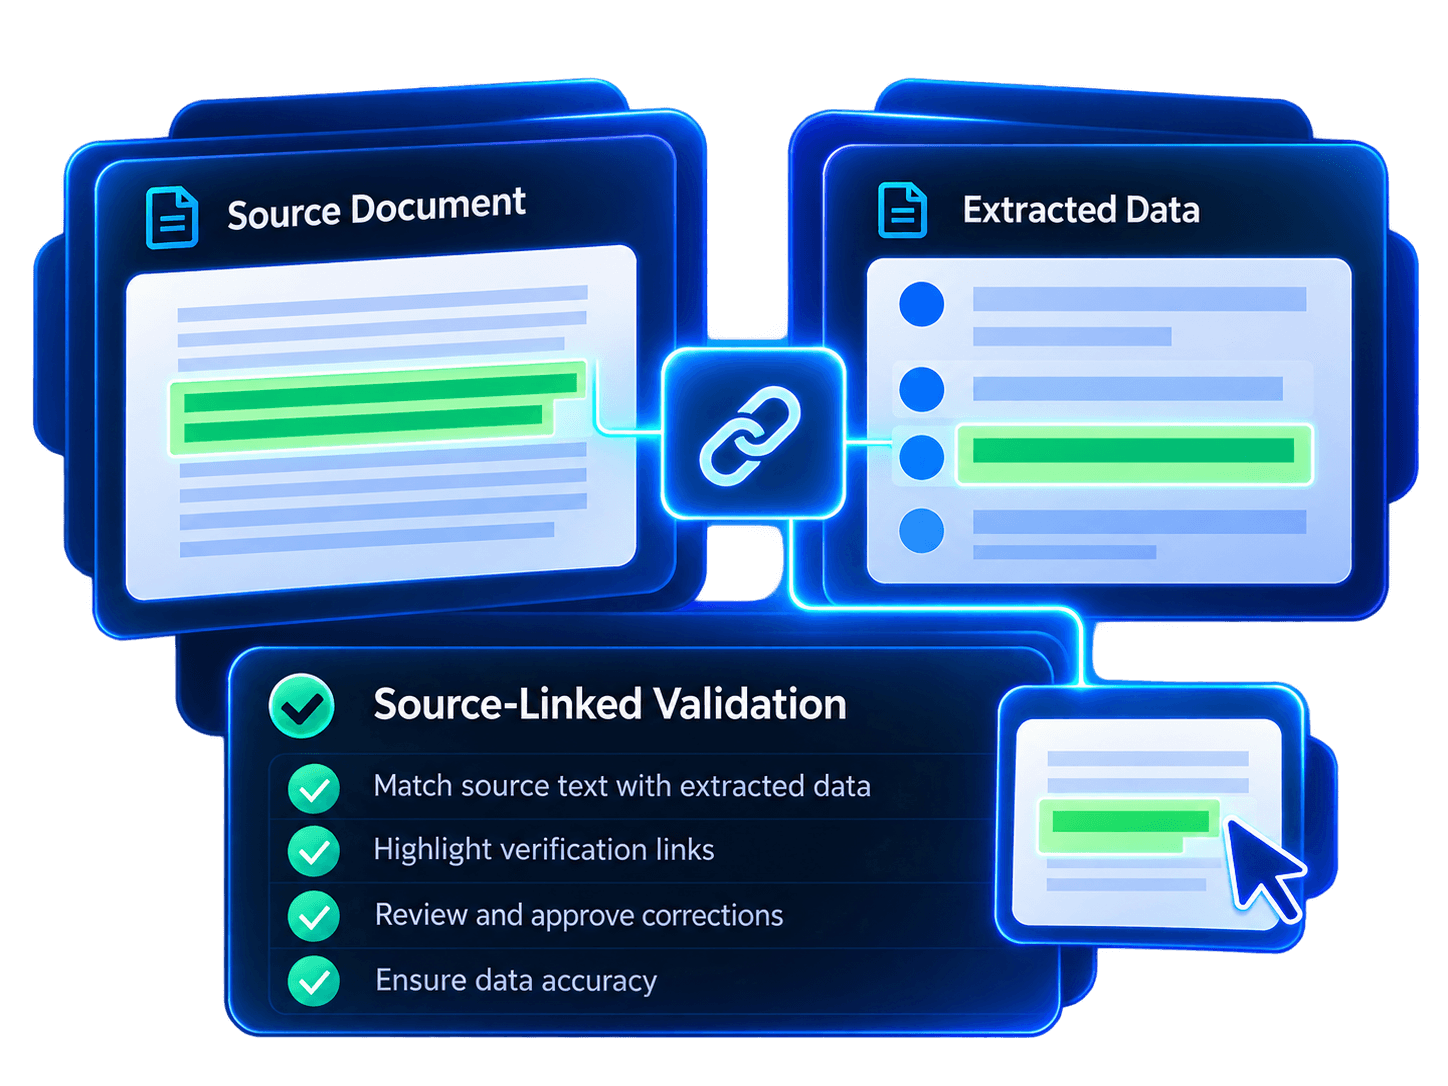
I brought table validation into the Python and Docling parser so that extraction errors could be investigated at the point where they occurred. The parser distinguishes rules that flag a table for review from rules that convert invalid tables to text. An audit trail records each conversion.
The engineering problem
A corrupt font can make one page’s text layer unreadable while the rest of the filing parses correctly. Reprocessing the entire PDF would repeat extraction on pages that had already passed validation.
How the system works
- Run the table validation rules on the extracted output.
- For a page with font-corrupted text, extract it again with OCR and compare the two validation scores.
- Use the OCR output only if its validation score improves. Keep flag-only results available for review.
Tools & Technologies
Python · Docling · OCR · jq · SQL · MySQL · Slack alerts · cron
Project illustrations use sample data.