Project overview
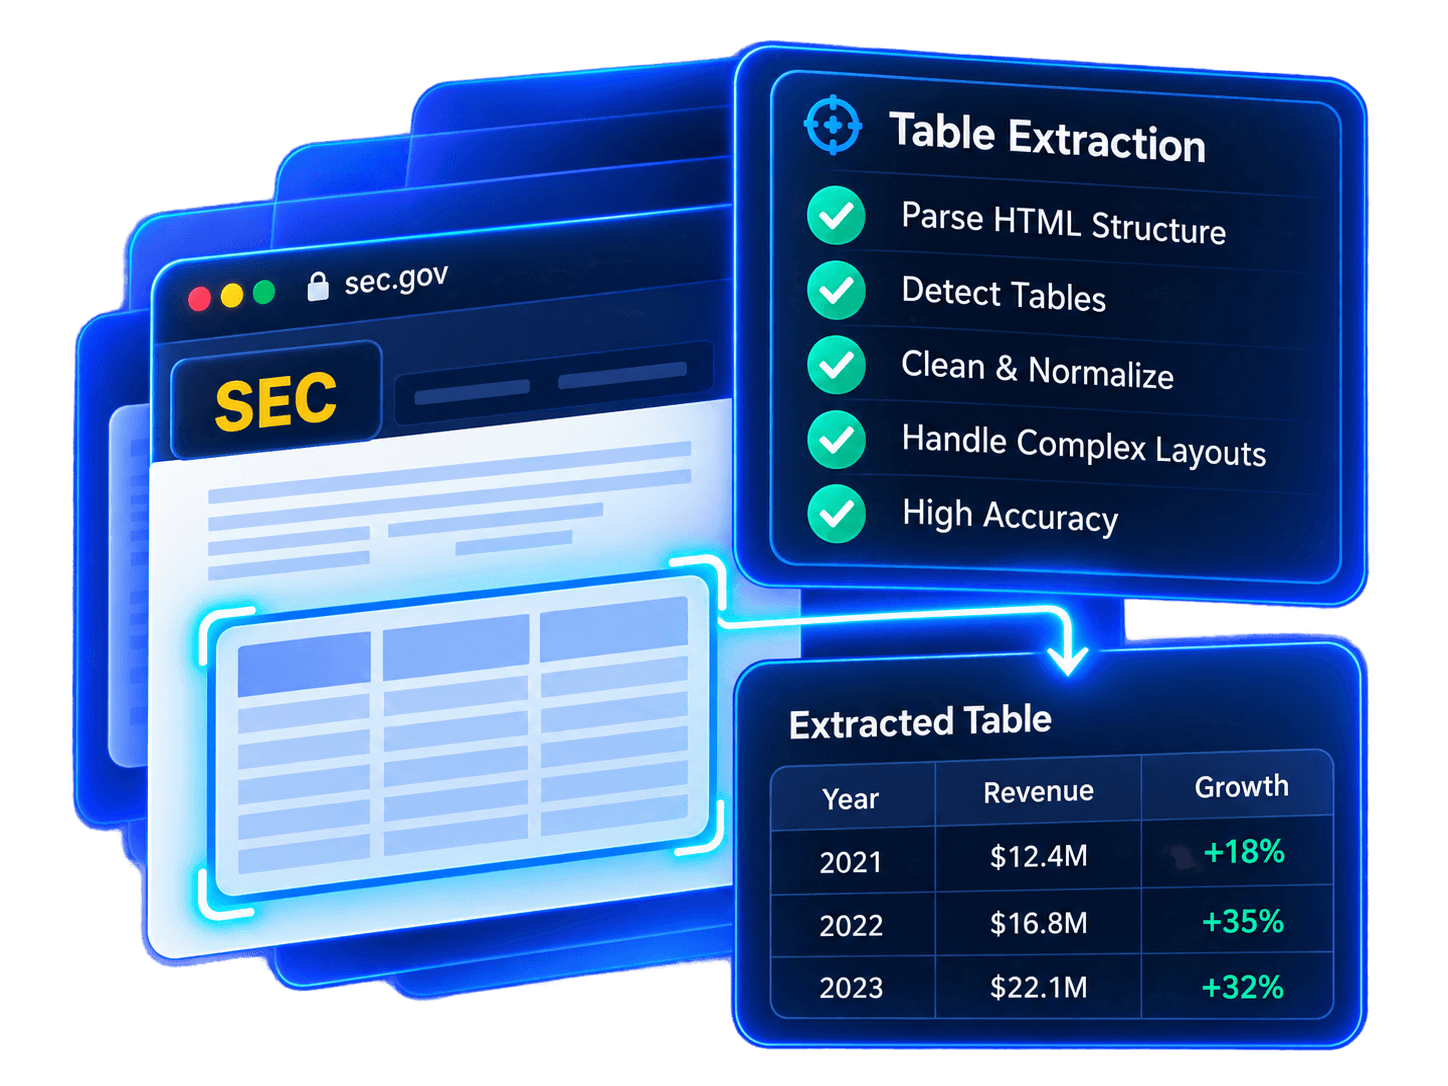
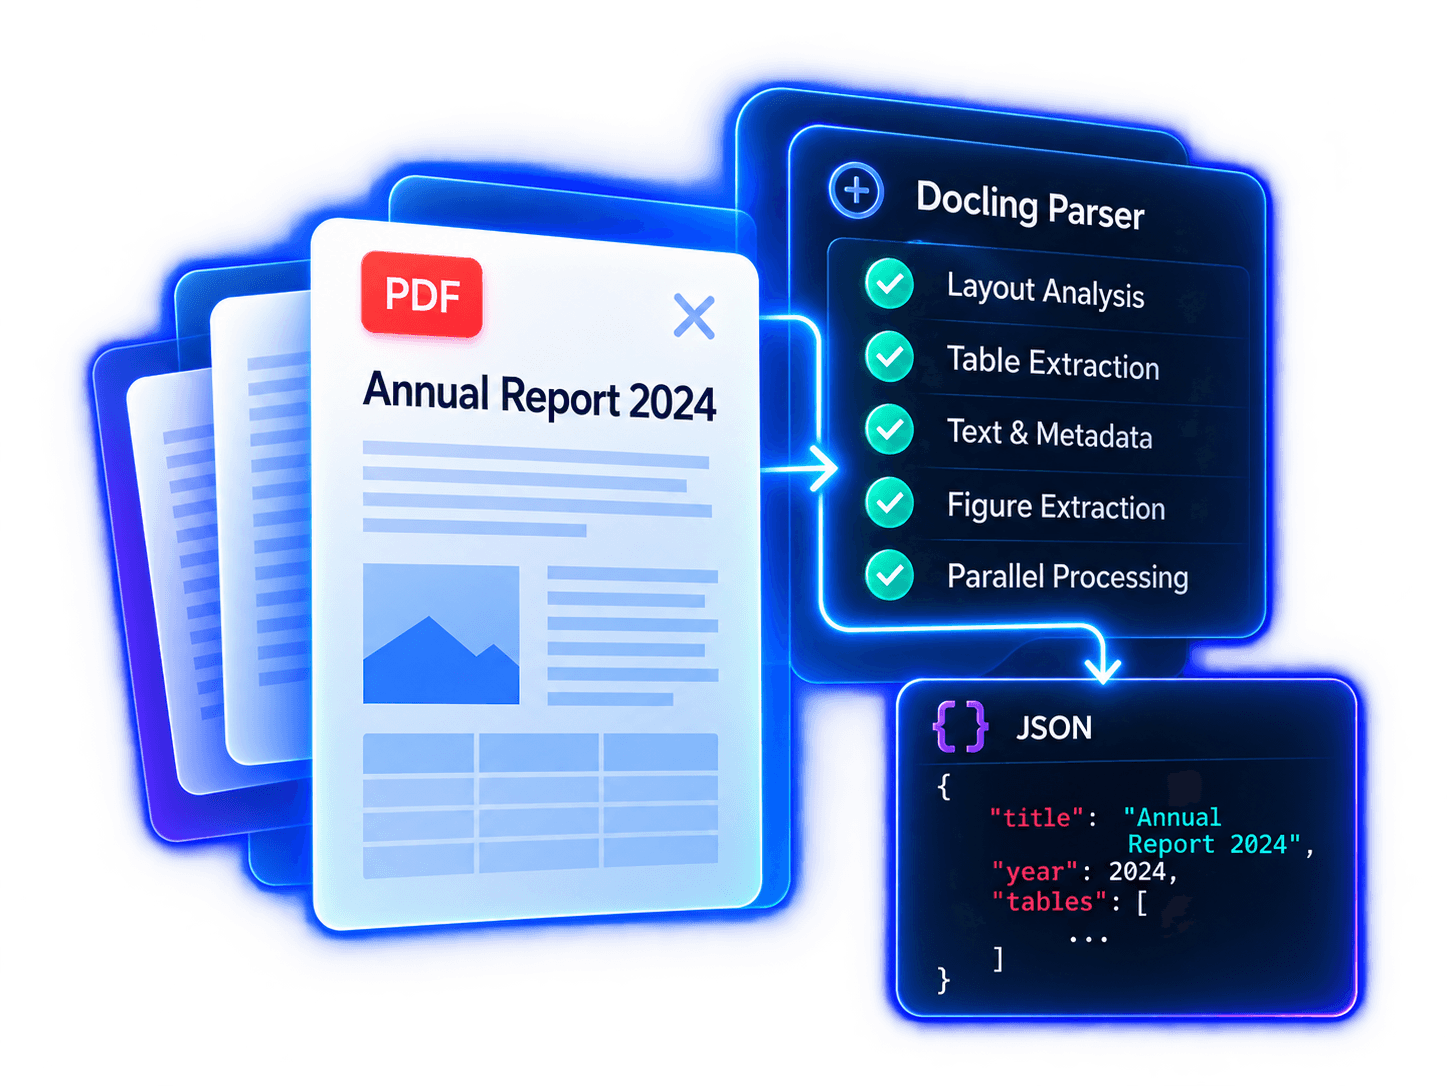
Maintain and extend the production PHP/Node.js parser that turns filings and PDFs into hierarchical JSON: HTML cleaning in headless Chrome, bold-level, table-of-contents and generic heading detection, and a PDF-to-HTML chain (custom pdftohtml jar, Tesseract OCR) tuned per document from MySQL configuration. Runs up to 50 parallel worker processes; fixed defects in item-heading detection and in files failing during batch reprocessing.
Tools & Technologies
PHP 7.2 · Node.js · Java · Puppeteer (headless Chrome) · Tesseract · MySQL · Bash · cron
Project illustrations use sample data.